I am a first-year M.Sc. student at the University of Chinese Academy of Sciences (UCAS), admitted through the recommendation (推免) program. I received my B.Eng. from Northeastern University, where I ranked 4 / 80 (top 5%). My research centers on computer vision and multimodal large language models (MLLMs), with a particular focus on controllable image editing and generation — building models that faithfully follow human intent expressed through masks, instructions, and natural language. I am also interested in diffusion-model acceleration / distillation and unified generation–understanding models.
I am currently a research intern at the Xiaohongshu (RED) AIGC Algorithm Group, where I contribute to the FireRed-Image-Edit foundation model. My first-author work FlexEdit (submitted to Pattern Recognition, SCI Q1) marries free-shape masks to a vision large language model for flexible, instruction-driven image editing.
You can find my work on Google Scholar (total citations 0+) 
🔥 News
- 2026.02: 🎉🎉 The FireRed-Image-Edit 1.0 technical report, which I co-authored during my internship at Xiaohongshu, is released on arXiv.
- 2025.12: 💼 I joined the Xiaohongshu (RED) AIGC Algorithm Group as a research intern.
- 2025.09: 🎓 I started my M.Sc. at the University of Chinese Academy of Sciences (UCAS).
- 2025.06: 📄 Our work on infrared gas semantic segmentation is published in Engineering Applications of Artificial Intelligence (SCI Q1).
- 2024.08: 🎉🎉 My first-author paper FlexEdit is released on arXiv.
📝 Publications
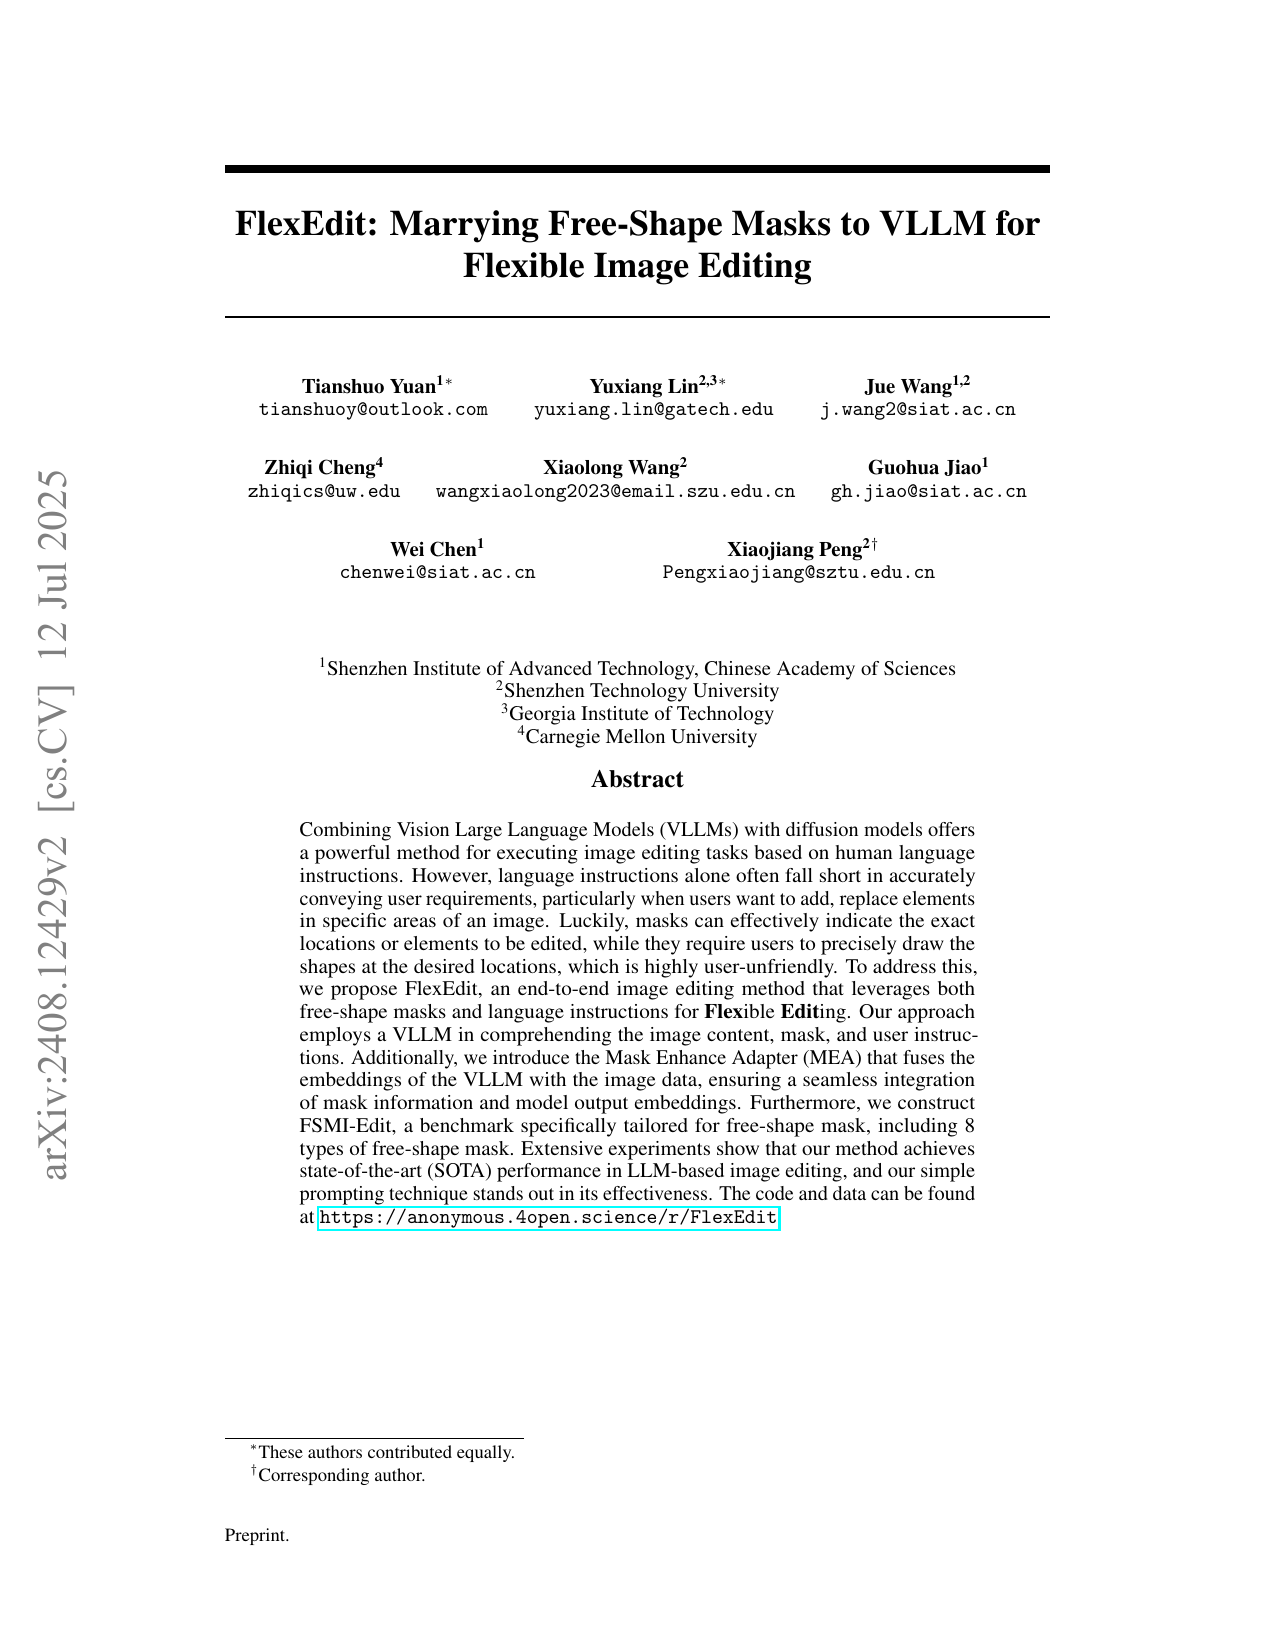
FlexEdit: Marrying Free-Shape Masks to VLLM for Flexible Image Editing
Tianshuo Yuan, Yuxiang Lin, Jue Wang, Zhiqi Cheng, Xiaolong Wang, Guohua Jiao, Wei Chen, Xiaojiang Peng
Tianshuo Yuan and Yuxiang Lin contributed equally; Xiaojiang Peng is the corresponding author.
Submitted to Pattern Recognition (SCI Q1) · arXiv
- An end-to-end framework that leverages both free-shape masks and language instructions, using a Vision Large Language Model (VLLM) to comprehend image content, masks, and user intent across replace / add / delete operations.
- We introduce the Mask Enhance Adapter (MEA) for seamless fusion of VLLM and image embeddings, and construct FSMI-Edit, a benchmark with 8 free-shape-mask types; FlexEdit achieves state-of-the-art performance in LLM-based image editing.
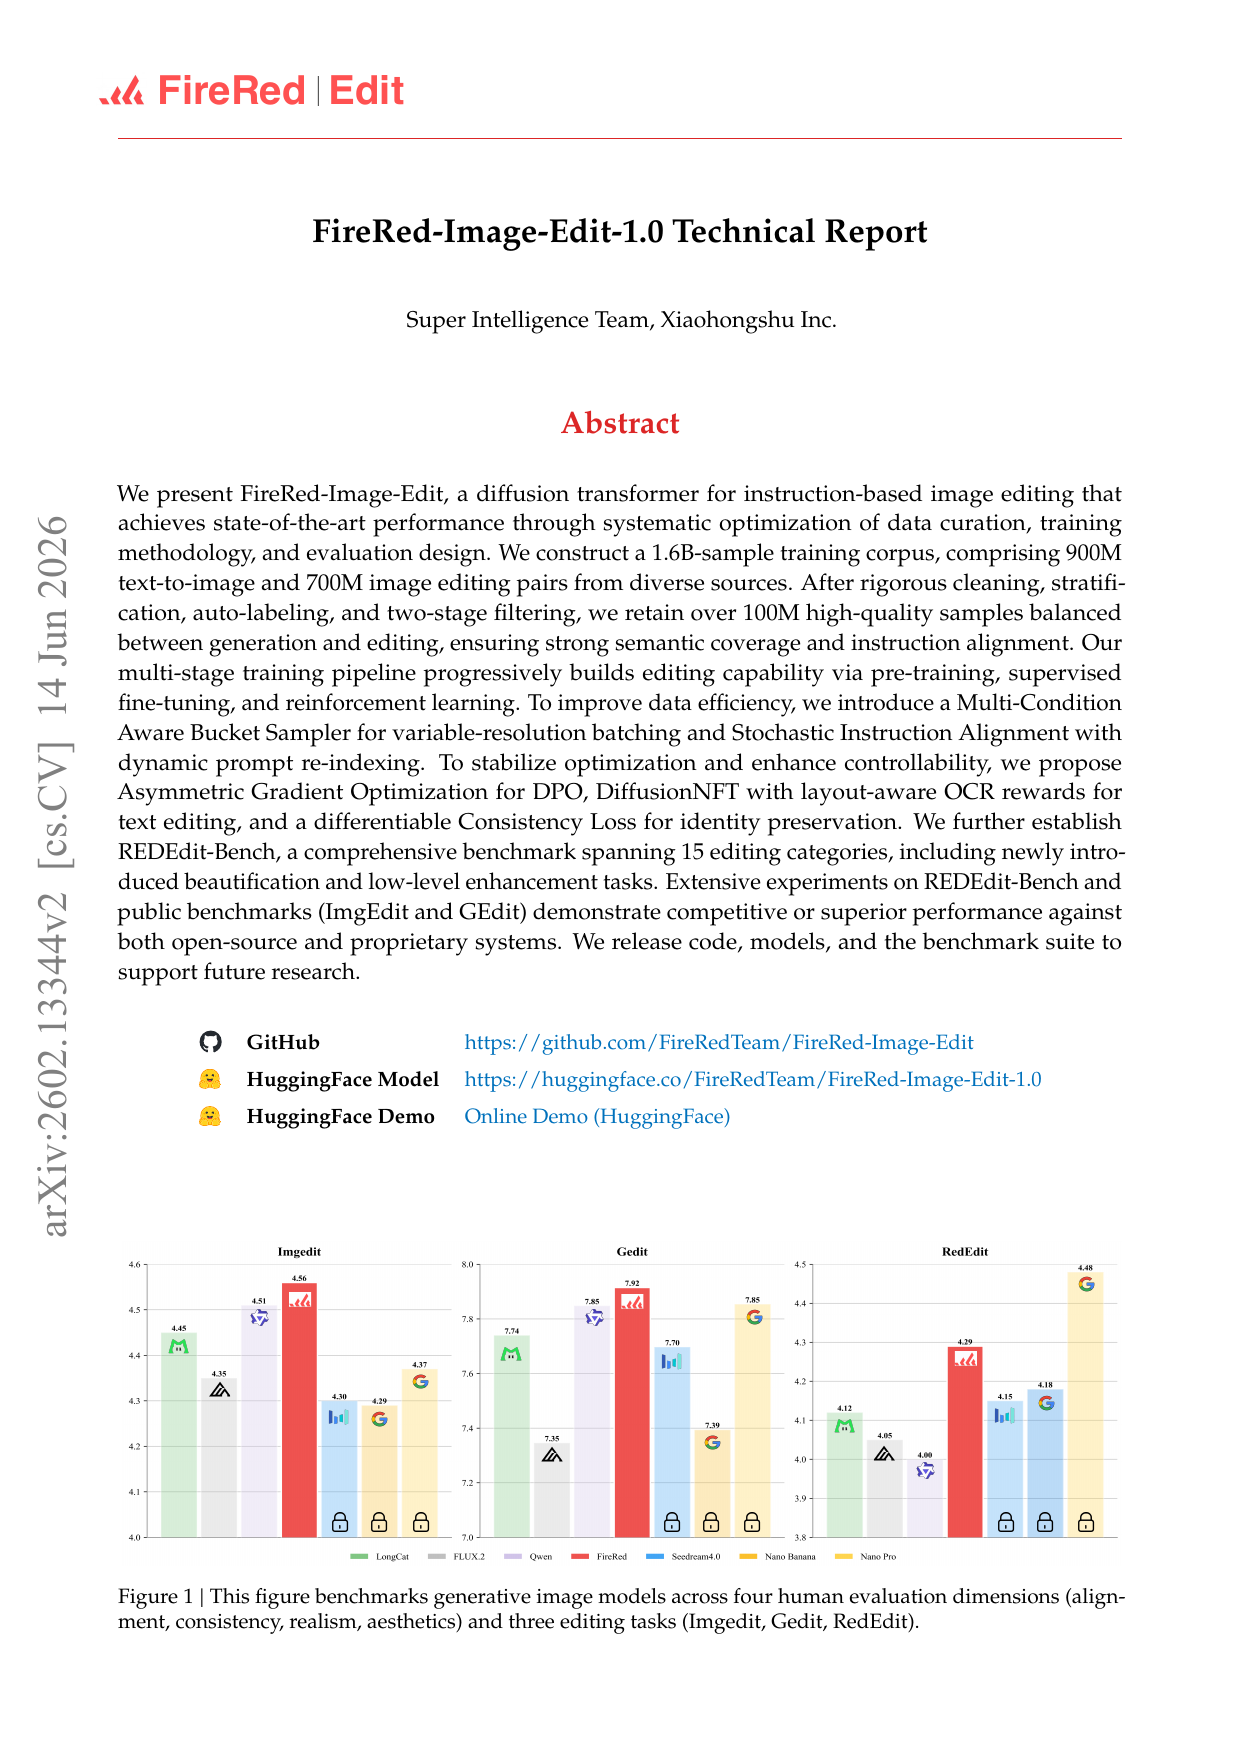
FireRed-Image-Edit 1.0 Technical Report
Super Intelligence Team, Xiaohongshu Inc. (incl. Tianshuo Yuan as contributor)
- A diffusion transformer for instruction-based image editing, trained on a 1.6B-sample corpus through a multi-stage pipeline (pre-training, supervised fine-tuning, and reinforcement learning).
- Introduces REDEdit-Bench, a benchmark spanning 15 editing categories, and achieves competitive or superior performance against leading open-source and proprietary systems.
Selected Publications
-
LeafConvNeXt: Enhancing Plant Disease Classification for the Future of Unmanned Farming, F. Lu, H. Shangguan, Y. Yuan, Z. Yan, T. Yuan, Y. Yang, H. Wang, W. Xie, et al., Computers and Electronics in Agriculture, 2025.
-
Contrast Gas Detection: Improving Infrared Gas Semantic Segmentation with Static Background, J. Wang, J. Fan, T. Yuan, D. Luo, G. Jiao, W. Chen, Engineering Applications of Artificial Intelligence, 2025.
-
A Cross-Modal High-Resolution Image Generation Approach Based on Cloud-Terminal Collaboration for Low-Altitude Intelligent Networks, M. Jiao, W. Jiang, T. Yuan, J. Wang, Y. Peng, Future Generation Computer Systems, 2024.
-
Person Re-Identification Based on Two-Layer Attention and Joint Learning, H. Zhu, M. Jiao, T. Yuan, W. Jiang, Int’l Conf. on Remote Sensing, Mapping, and Image Processing (RSMIP), 2024.
🎖 Honors and Awards
- Undergraduate, GPA ranking 4 / 80 (Top 5%), Northeastern University.
- Undergraduate, Second-Class Academic Scholarship, Northeastern University.
- Undergraduate, First-Class Scholarship, Northwest Institute for Nonferrous Metal Research.
📖 Educations
- 2025.09 - 2028.06 (expected), M.Sc., University of Chinese Academy of Sciences (UCAS), Beijing, China. (Admitted via recommendation, 推免)
- 2021.09 - 2025.06, B.Eng., Northeastern University, Shenyang, China. (GPA rank 4/80, Top 5%)
💻 Experience
- 2025.12 - 2026.05, Research Intern, Xiaohongshu (RED) — AIGC Algorithm Group, Beijing, China.
- Contributed to the FireRed-Image-Edit 1.0 foundation model and co-authored its technical report.
- Built REDEdit-Bench and iterated a DMD acceleration-distillation framework; trained 4-/8-step distilled models (v0.3) that improved ImgEdit-benchmark performance and reduced generation artifacts, enabling efficient inference for the v1.1 release.
- Investigated unified generation–understanding models: reproduced and trained Bagel and Show-o2, and designed a CoT / dense-caption data pipeline to improve comprehension of complex editing instructions.